

dsh-llm-latency
Manifest validNo project description is available for this repository yet.
dsh-llm-latency
Per-vendor / per-model / per-session LLM latency and cache-hit telemetry for DeepSeek Harness. It answers with numbers: "which vendor is actually faster, and whose cache hits better — for the same model, over the same period?"
- Passive telemetry — every real model call is measured (first token, end-to-end, tokens/sec, cache-hit share) and classified by failure kind (429 / timeout / 5xx / abort).
- Three comparisons:
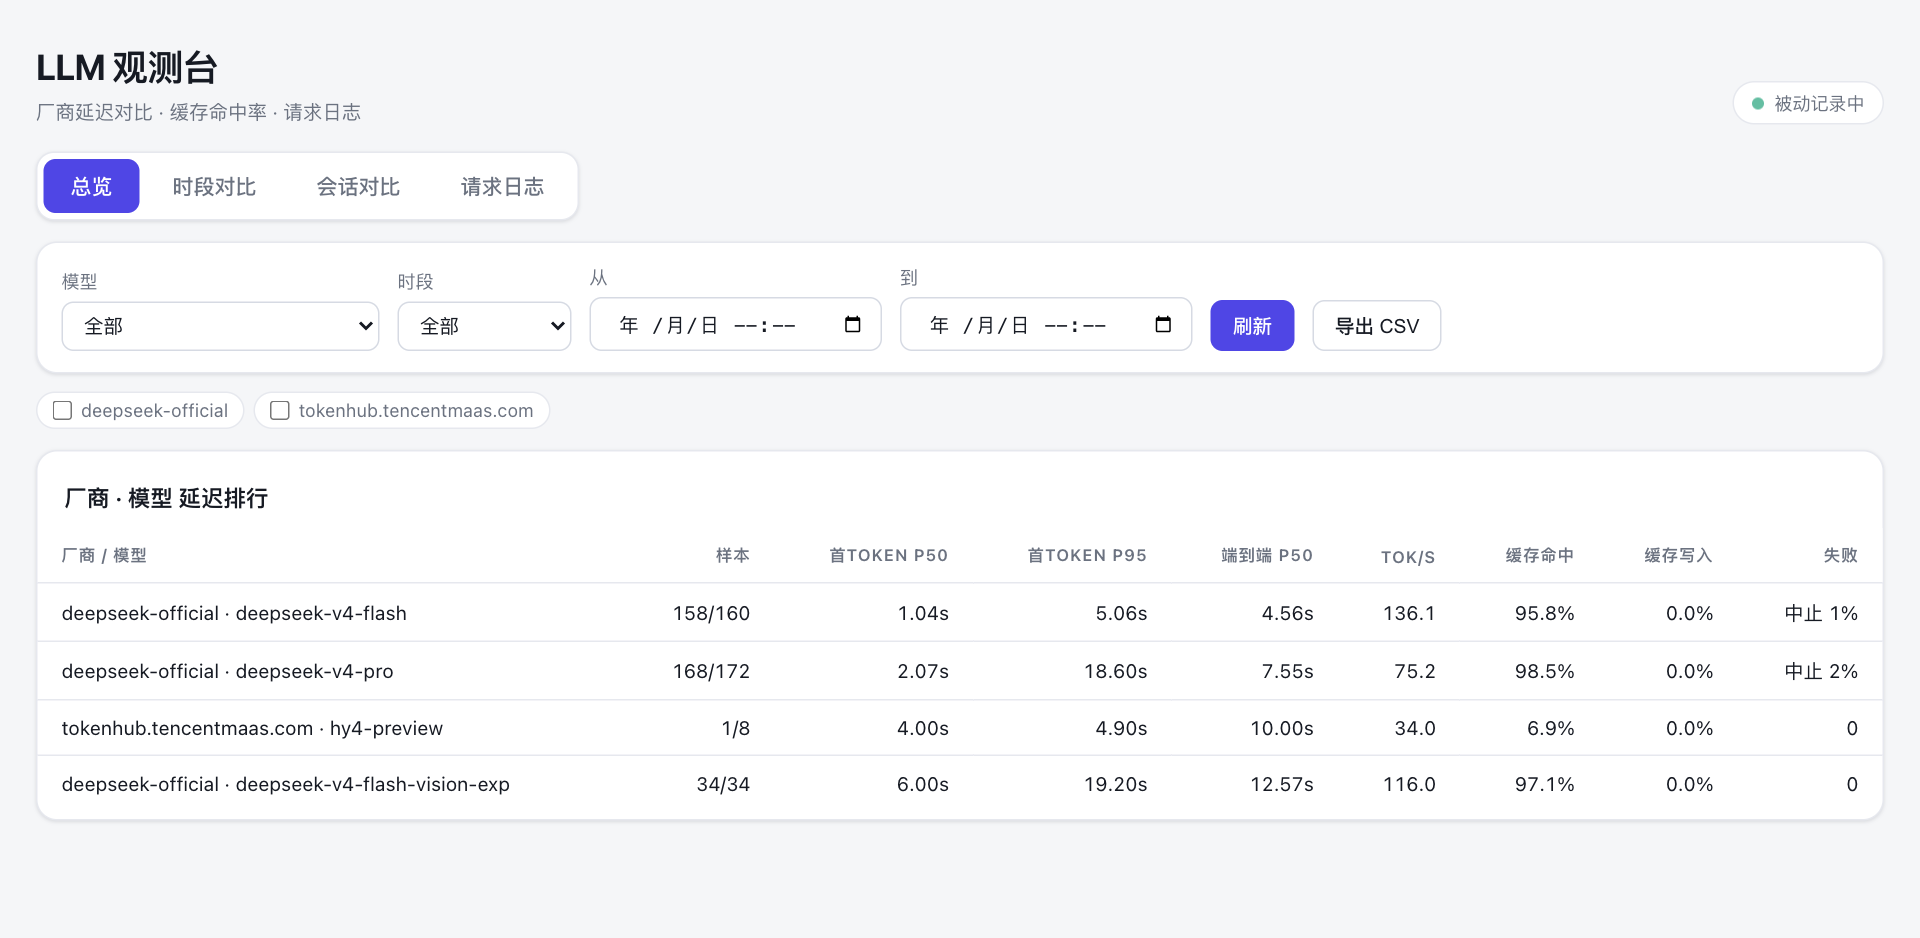
- Overview — rank all vendor·model rows over any time window.
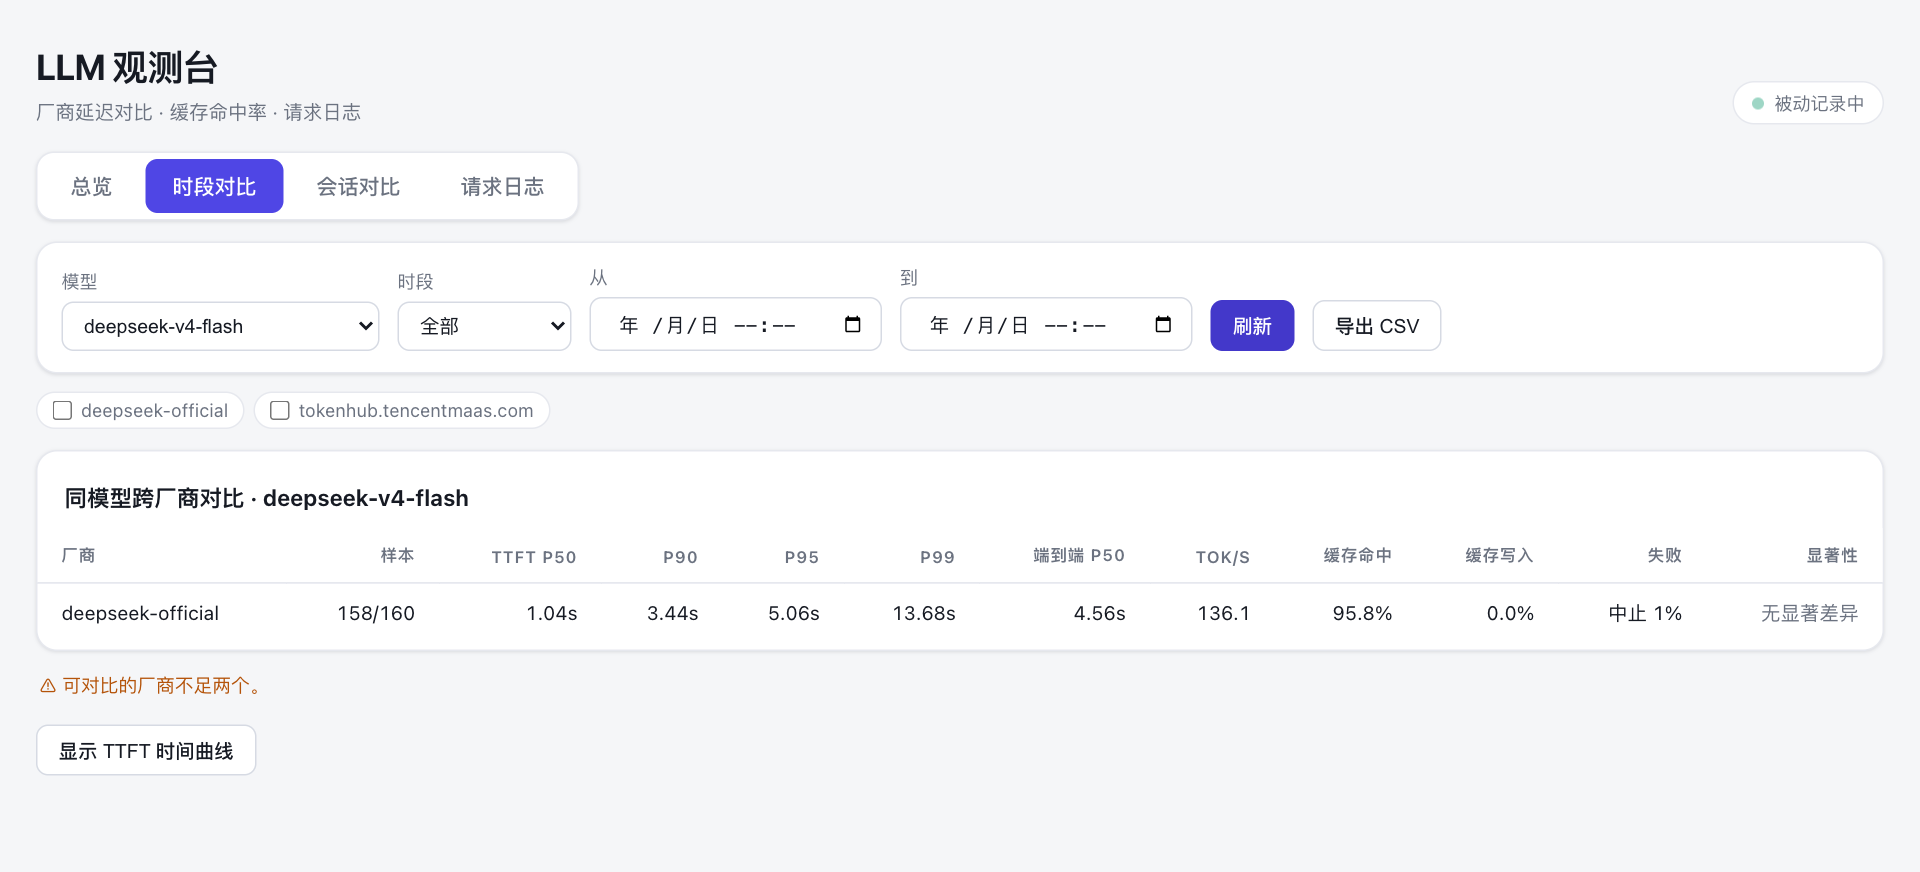
- Time-window — same model across vendors over an arbitrary window (e.g. today 10:00–10:30), with P50/P90/P95/P99, failure rates, cache-hit rate, sample counts, and median significance.
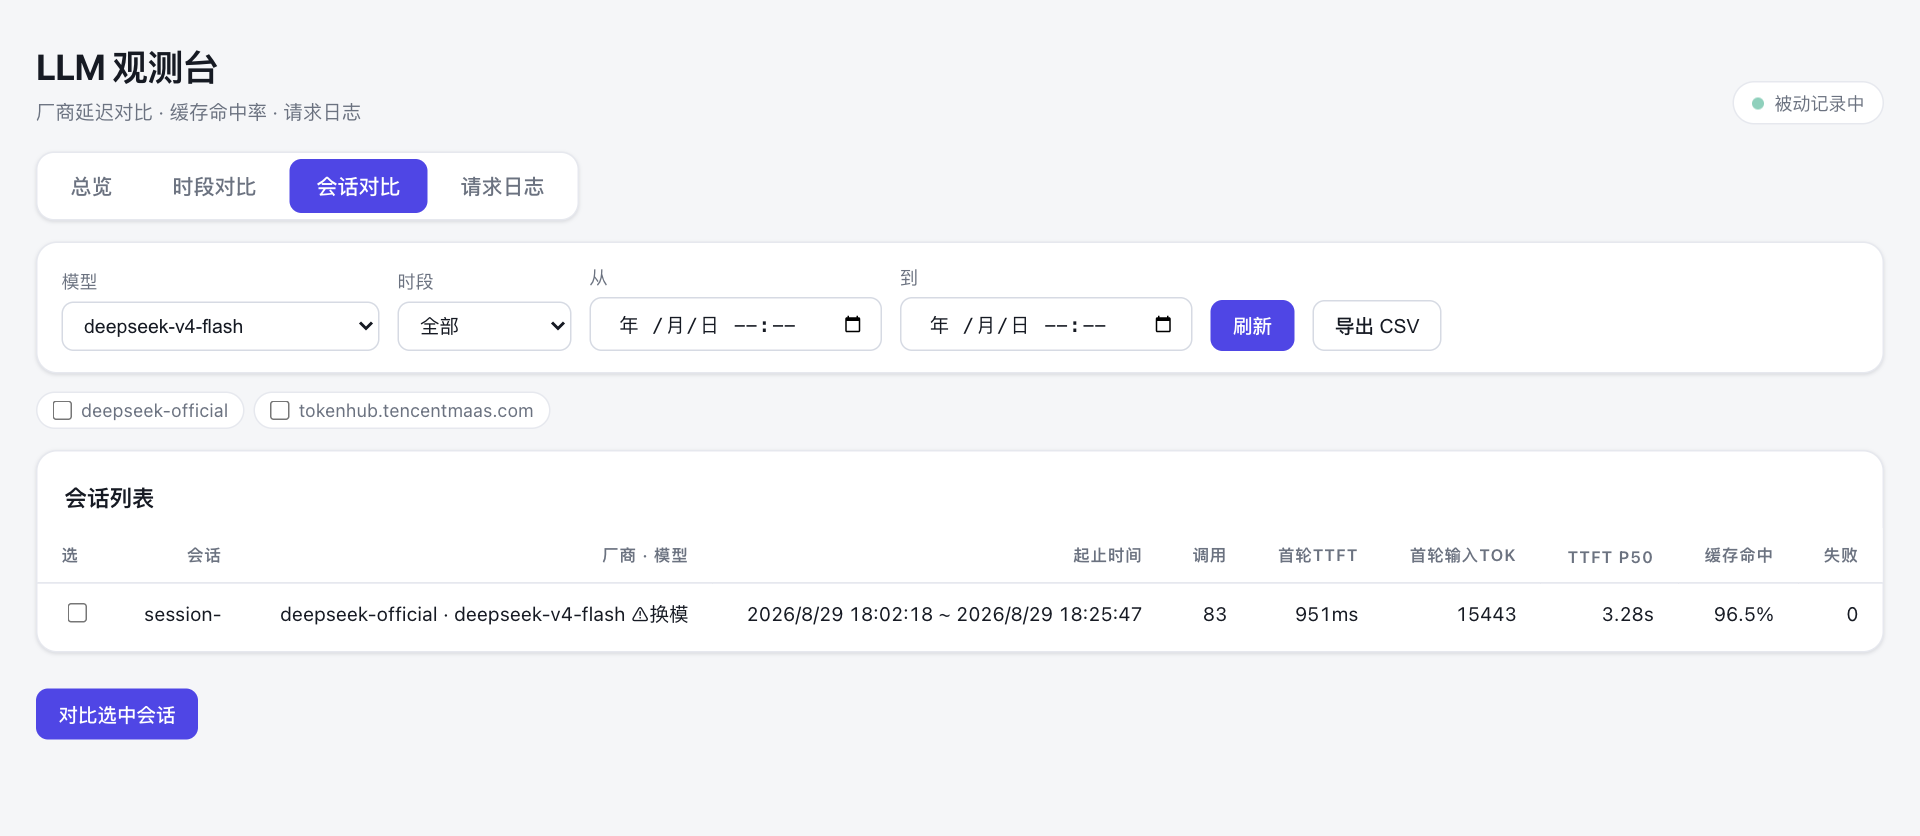
- Session — run the same prompt in two sessions, each pinned to one vendor's model, then compare the whole runs; valid only when a session never switched models.
- Dashboard + tool — a self-contained HTML dashboard (overview / time-window
/ session / request-log views) plus the
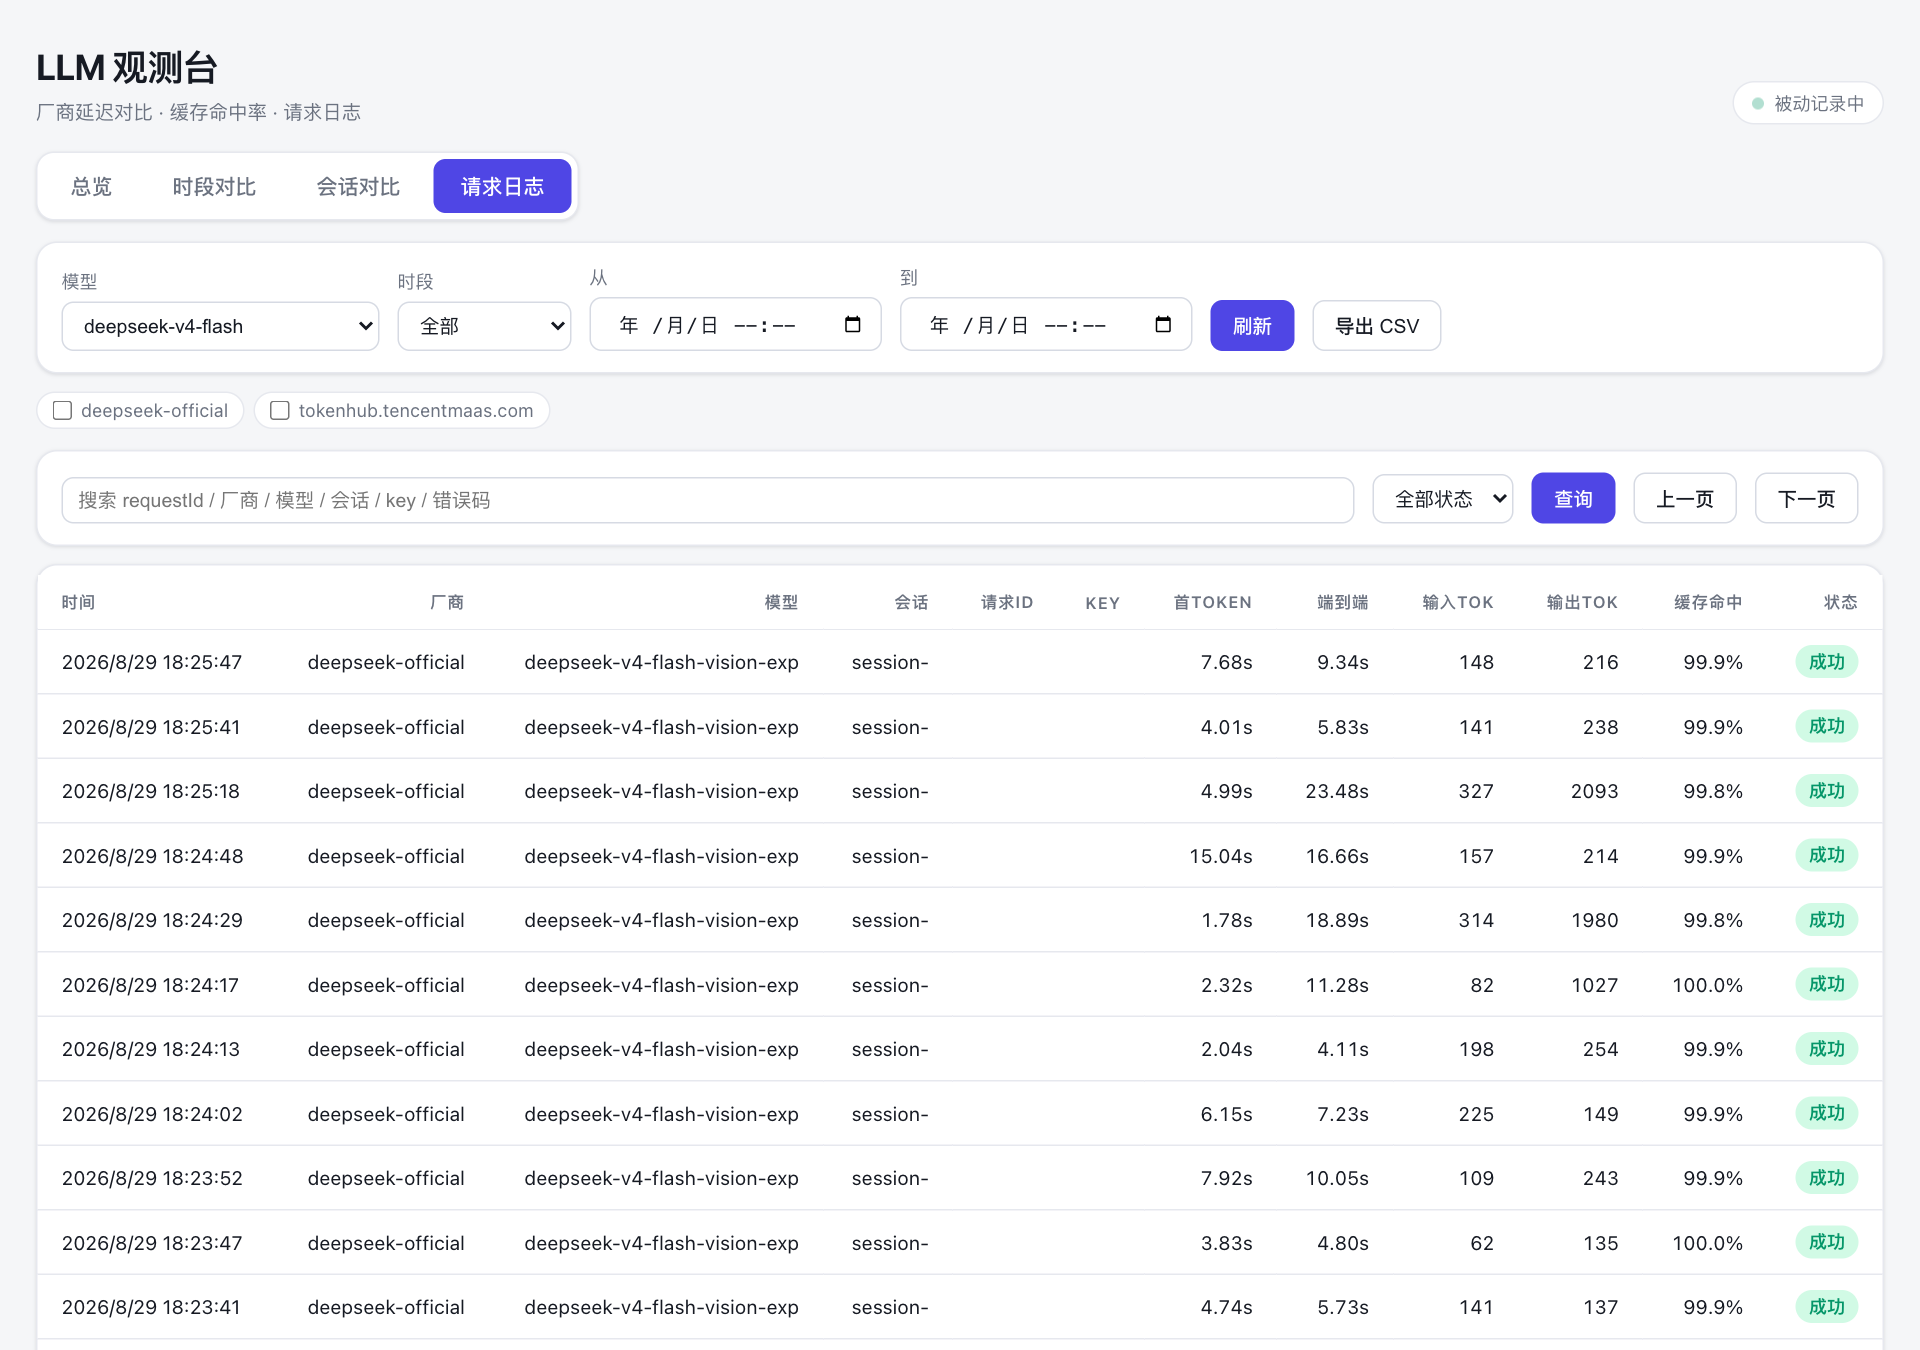
latency_reportmodel tool and CSV export. - Request log — every model call is persisted as one record (time, vendor, model, session, request id, credential ref, TTFT, end-to-end, input/output tokens, cache-hit rate, status), searchable and filterable in the dashboard.
See DESIGN.md for the data model and comparison methodology.
Screenshots
Overview — rank every vendor·model row over a time window.
Time-window — the same model across vendors, with P50/P90/P95/P99, failure rates, cache-hit rate, and median significance.
Session — compare two single-model sessions side by side.
Request log — search and filter every model call.
Install
dsh plugin --profile web add github:shengbinxu/dsh-llm-latency
Then restart the profile. The plugin applies after dsh-base (it needs the
llm service), intercepts llm/stream, and serves the dashboard at:
http://127.0.0.1:3080/llm-latency/
Usage
- Dashboard — switch between 总览 / 时段对比 / 会话对比 / 请求日志:
- 时段对比: pick a model, pick a window, compare vendors side by side.
- 会话对比: pick two sessions that each used a single model, compare them.
- 请求日志: search and filter every model call by request id, vendor, model, session, credential ref, or status.
- Model tool — ask the agent "帮我看看各厂商延迟对比" (
latency_report); it acceptsmodel,vendors,from/to, andsessionIds.
Where data lives
Aggregates persist at $DSH_HOME/llm-latency/stats.json (default
~/.dsh/llm-latency/stats.json). Delete the file to reset. The request log is
append-only at $DSH_HOME/llm-latency/requests.jsonl.
Metrics
- TTFT (primary) — time to first content chunk; e2e — full stream; tok/s — decode throughput.
- Cache-hit rate —
cacheRead / (input + cacheRead + cacheWrite); cache-write rate —cacheWrite / (input + cacheRead + cacheWrite). - Failure breakdown — 429 (rate-limited), timeout, 5xx, abort, other, each
as a share of attempts. Retries are separate
llm/streamcalls, so a 429 is recorded as an attempt-level failure.
Comparison methodology
Same-model cross-vendor comparisons always slice every vendor to the same
time window. Percentiles come from merged histograms; the median's 95%
bootstrap confidence interval comes from the recent sample ring when the window
has enough samples (minSamplesForComparison). Two vendors differ
significantly when their median CIs do not overlap. Insufficient samples and
gross sample imbalance are flagged.
Configuration
Set in cordis.patch.yml (or override the row):
| Key | Default | Meaning |
|---|---|---|
retentionDays | 30 | Data retention window in days |
recentLimit | 2000 | Per-key exact-sample ring cap |
sessionLimit | 500 | Sessions retained (most recent first) |
spikeFloorMs | 10000 | TTFT above this counts as a spike |
modelAliases | {} | Canonical model → provider model ids |
minSamplesForComparison | 20 | Minimum ok samples before a median CI is reported |
logLimit | 5000 | Request-log mirror cap (recent records kept) |
logRetentionDays | 7 | Request-log retention window in days |
How it works
The plugin registers a waterfall listener on llm/stream, wraps the returned
AsyncIterable<StreamChunk>, and starts its clock on the first pull — the
moment the adapter lazily issues the HTTP request. Failures carry the harness
LlmFailure.code/.status, mapped to the five-class taxonomy above.
License
MIT
Comments
Loading…
From the same category
by ranxianglei
基本稳定可用 100K tokens is enough. Universal context-compression proxy for ALL AI coding agents,10w上下文足矣
★ 814
↓ 423.4k/wk
MIT
TypeScript
Oct 11, 2026
dsh plugin --profile web add billion-contextby Han-1413141
DeepSeek Harness session cost meter plugin: session/daily cost, budget, history, OpenCode Go quota, official & custom-provider balance, Codex-like token heatmap, peak/off-peak pricing with pre-switch
★ 388
↓ 23k/wk
MIT
JavaScript
Oct 10, 2026
dsh plugin --profile web add dsh-cost-meterby Nwflower
Import 14+ external agent chat histories (Claude Code, Codex, ChatGPT, Cursor, Gemini, Reasonix, opencode, ZCode, Grok Build, OpenClaw, Pi, Hermes, Kimi CLI, DSH) into DeepSeek Harness as resumable se
★ 224
MIT
JavaScript
Oct 7, 2026
dsh plugin --profile web add dsh-chat-importby Totoro-qaq
DeepSeek Harness plugin for previewable cross-preset session migration. Fixed-schema handoffs preserve state, source-model intent, and unresolved images; the original session stays untouched.
★ 165
MIT
JavaScript
Oct 11, 2026
dsh plugin --profile web add dsh-plugin-bridgeby Anionex
deepseek harness对话和代码状态回退插件 | DSH — rewind conversation and workspace state, powered by a persistent Change Ledger
★ 131
BSD-3-Clause
JavaScript
Oct 1, 2026
dsh plugin --profile web add @anionex/dsh-turn-rewindby SiriLee
DSH 插件:真正便捷无感的同窗口内对话回退,从不新建分支;自带轻量工作区备份,可一并还原文件(完整 Claude Code /rewind 语义)。 · DSH plugin: genuinely effortless in-window conversation rewind — never forking a new session; ships a lightweight workspac
★ 123
↓ 5.5k/wk
MIT
TypeScript
Oct 9, 2026
dsh plugin --profile web add dsh-rewind-plugin